 TITANIUM COMPUTING
(512) 623-9199
Free consultation
TITANIUM AI · APPLIANCE · SOFTWARE
AINode. The Software That Runs the Box
Every Titanium Private AI appliance is driven by AINode, master control software we built in-house and run on our own cluster every day. One dashboard for the whole fleet: models, chat, APIs, training, and benchmarks. Made in Texas.
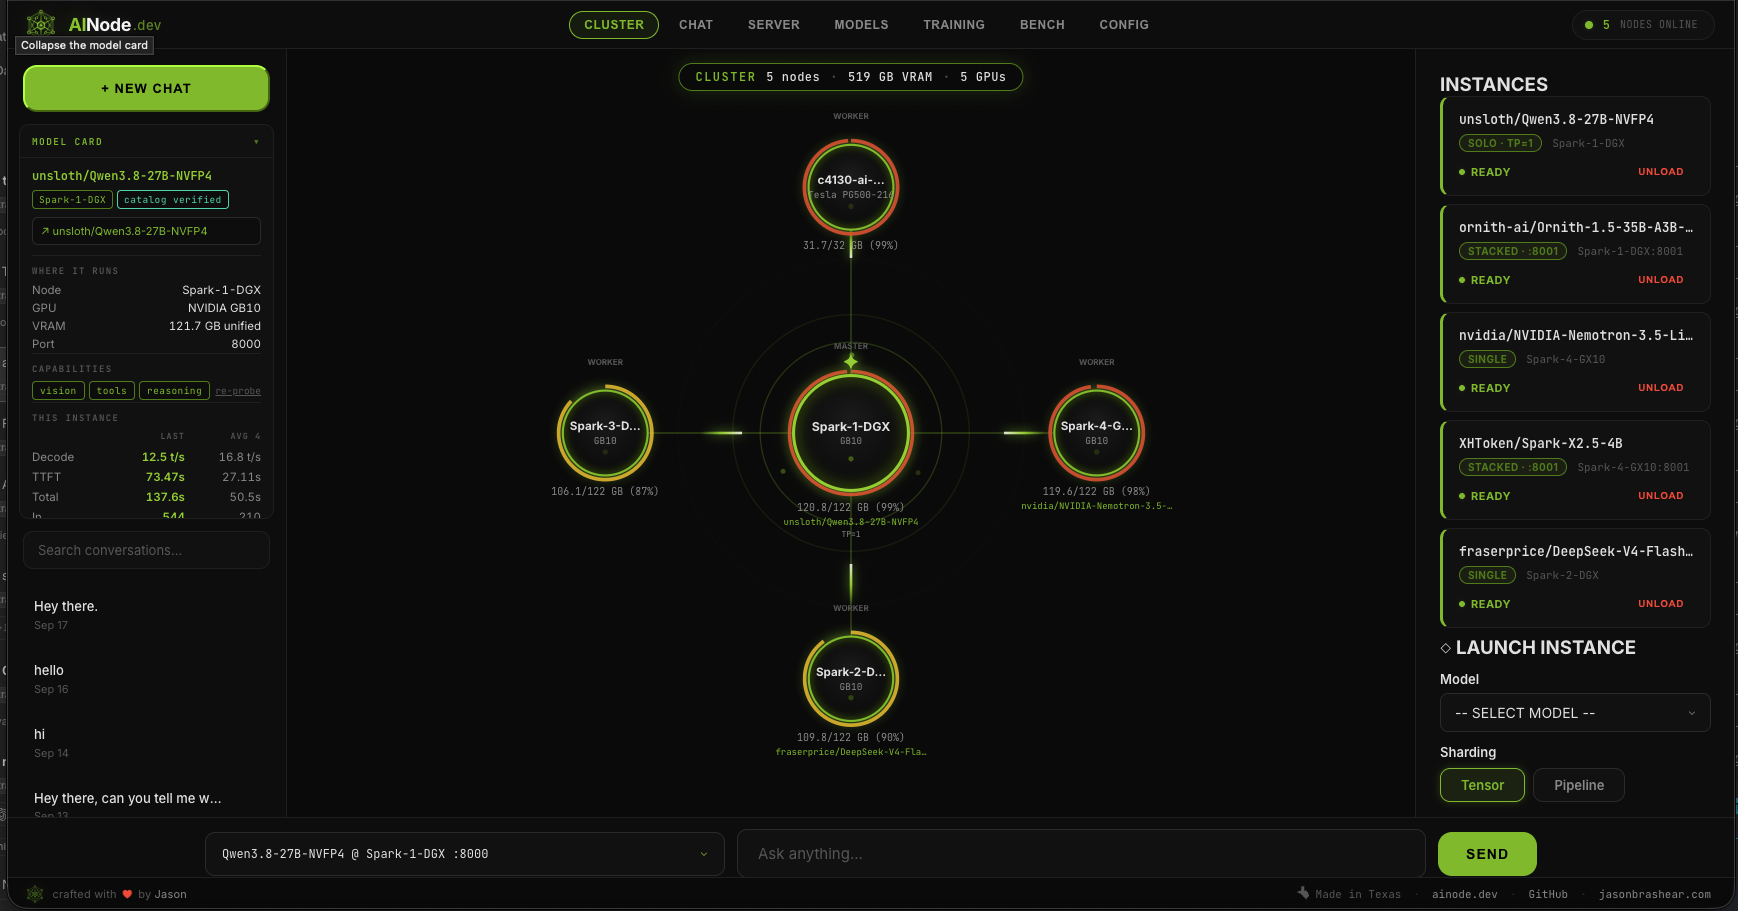
Your Whole AI Fleet on One Screen
The cluster view shows every node, every GPU, and every loaded model live, memory use, health, and which worker is serving what. This is the same console our engineers watch when they manage your appliance.
A Tour of the Screens
Live captures from our own cluster, not mockups.
Built-In Assistant & Model Playground
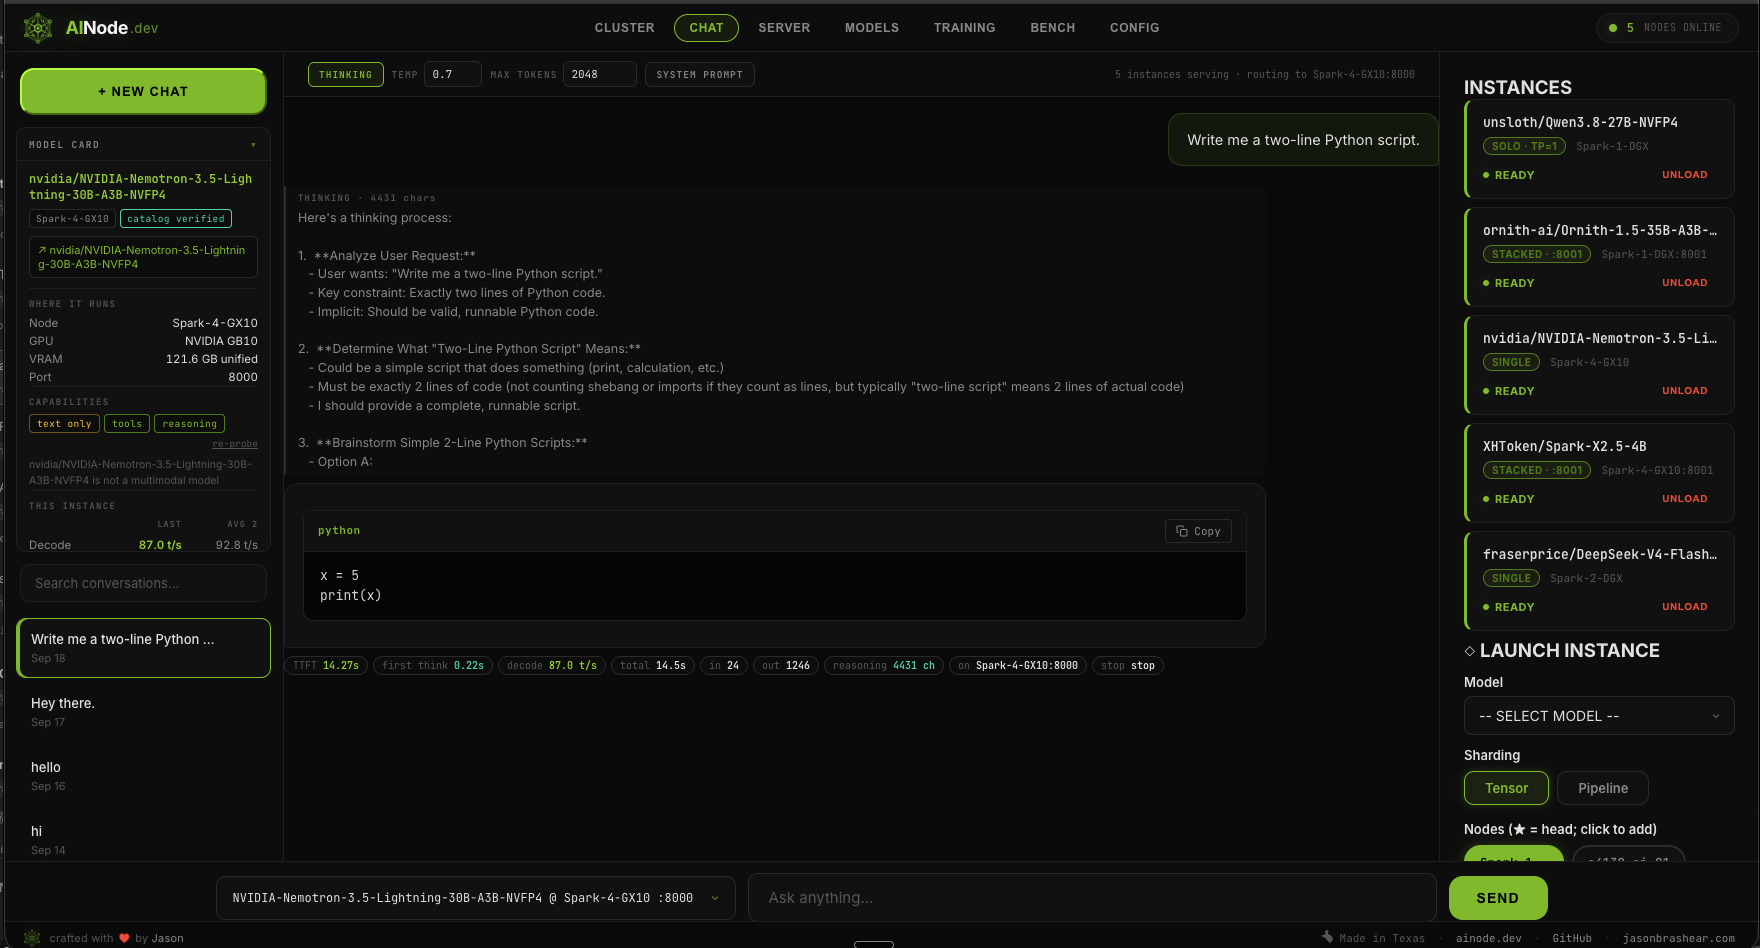
Staff chat straight against your own models, no third-party chat app. Pick any loaded model, set temperature and system prompts, watch the model's reasoning, and see exact speed stats on every response.
It doubles as a playground for experiments: switch models mid-conversation and compare how each answers before you commit one to a workflow.
Model Catalog
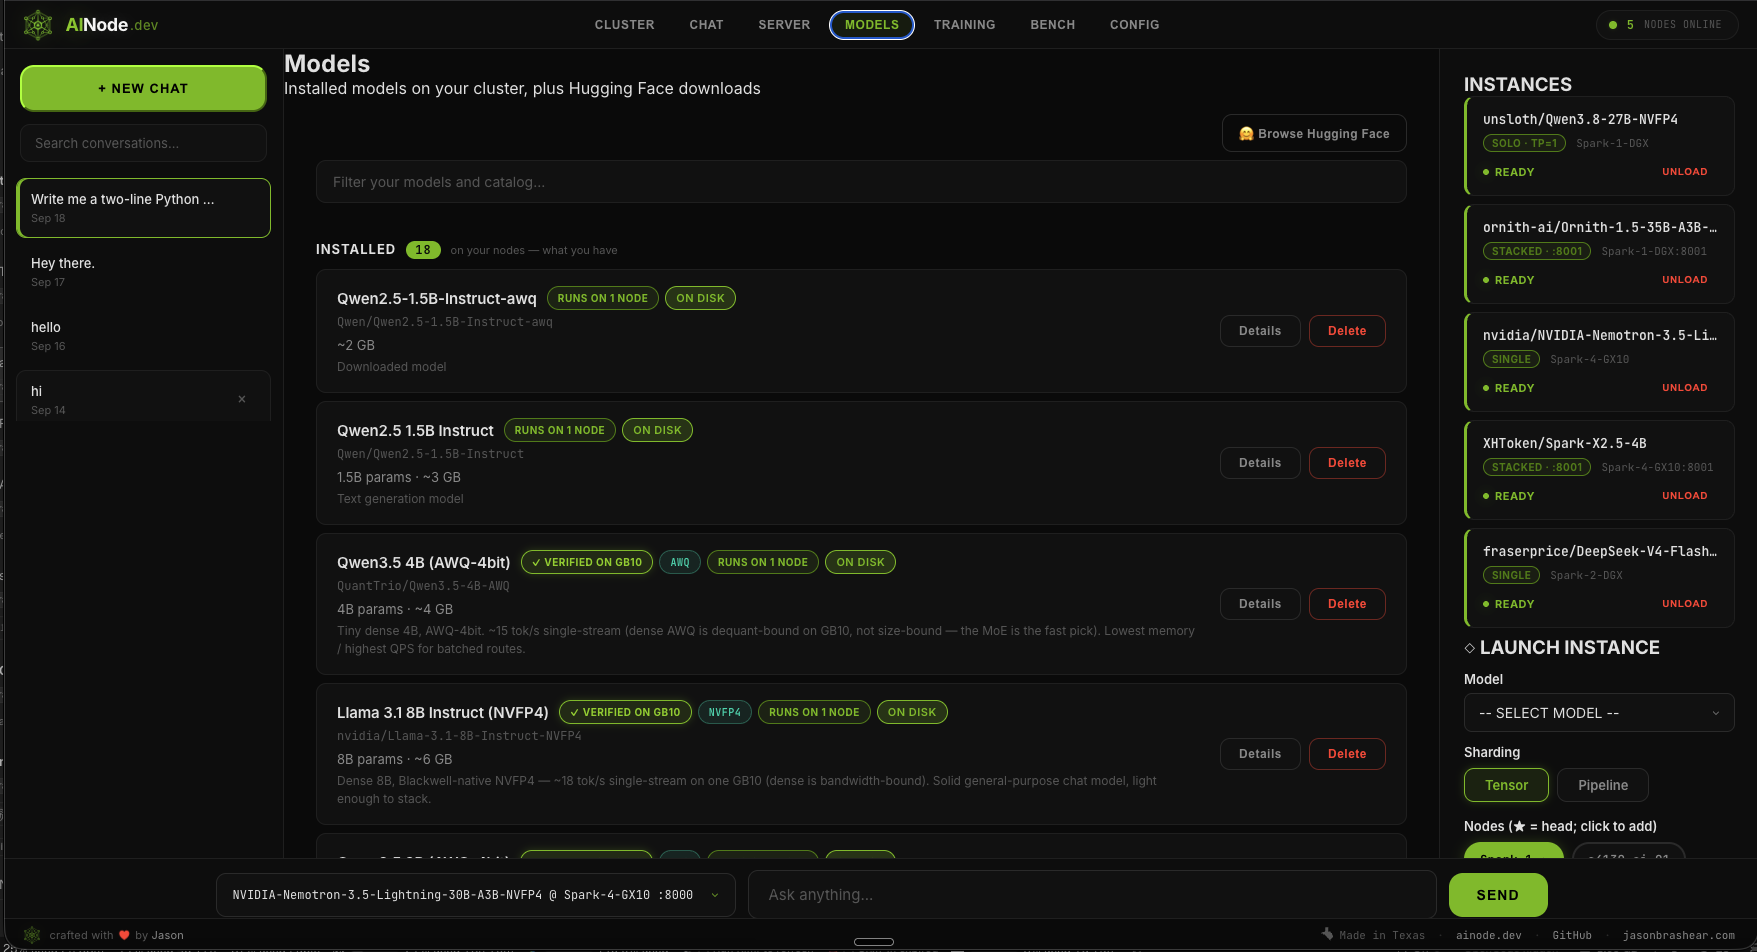
Every model installed on your cluster in one catalog, size, quantization, which node it runs on, and honest notes on how each performs on your hardware. Browse Hugging Face and download new models directly.
Verified badges mark models we've proven on the exact GPU in your appliance, so you know before loading what will run well.
Fine-Tuning On-Box
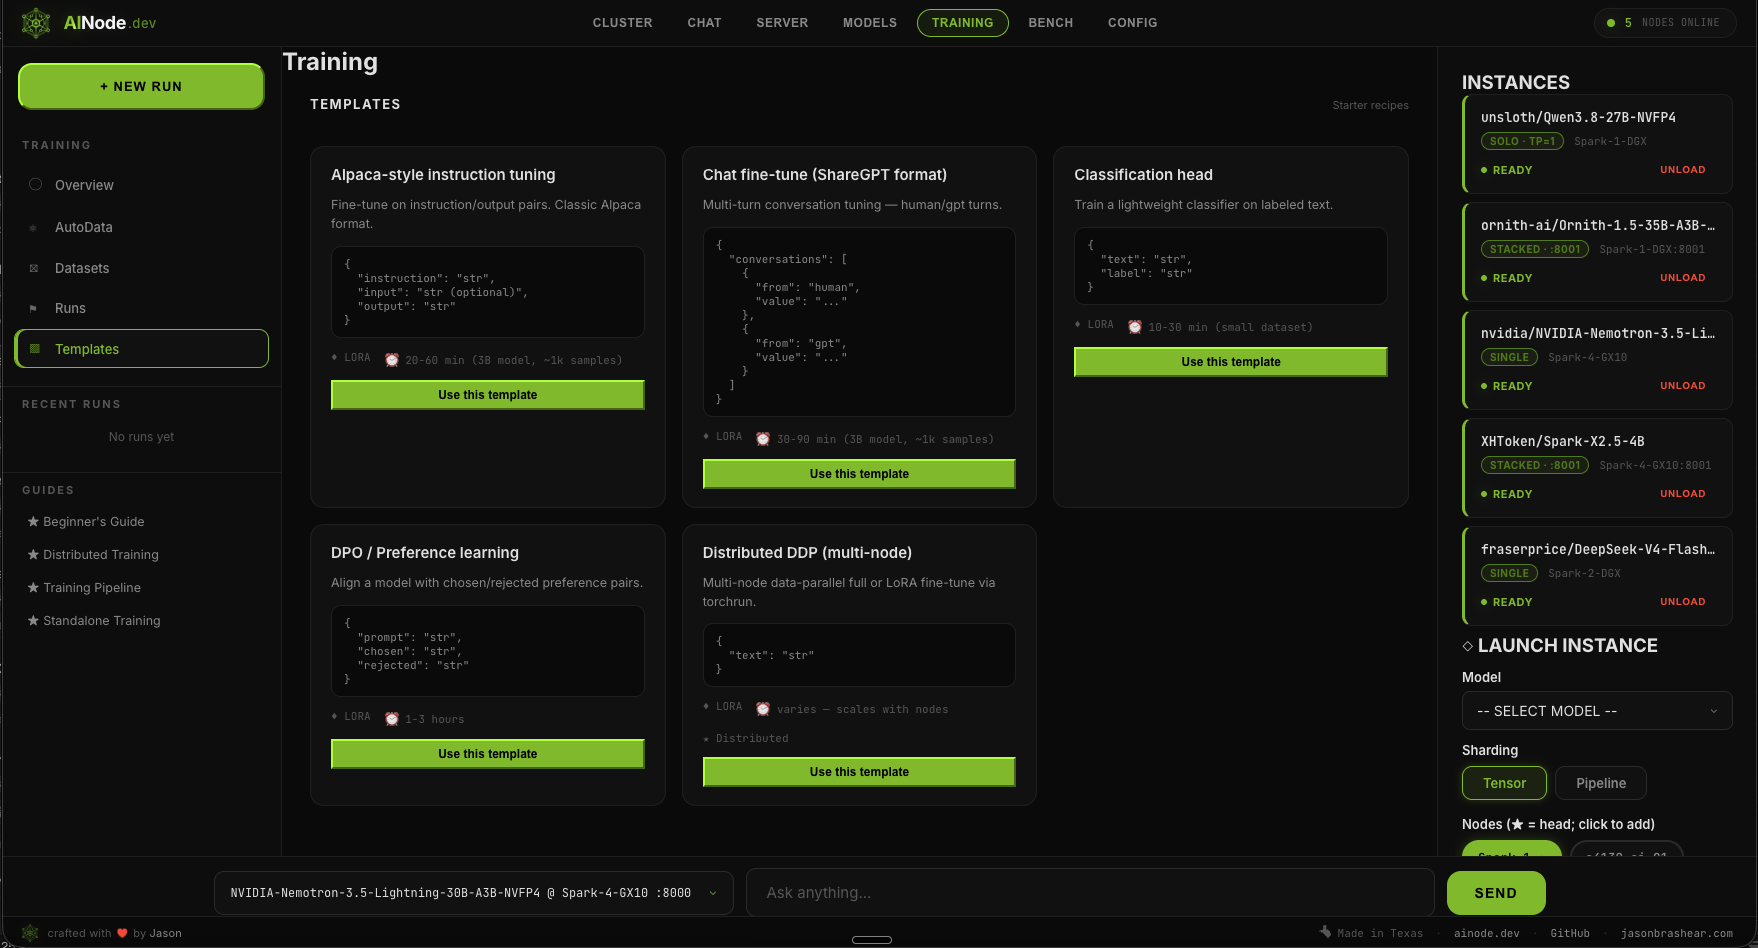
Train models on your own data without it ever leaving the building. Ready-made LoRA templates cover instruction tuning, chat fine-tunes, classification, and preference learning, most runs finish in under an hour.
Larger jobs scale across nodes with distributed multi-node training. Your firm's tone, terminology, and procedures become part of the model itself.
Honest Benchmarks
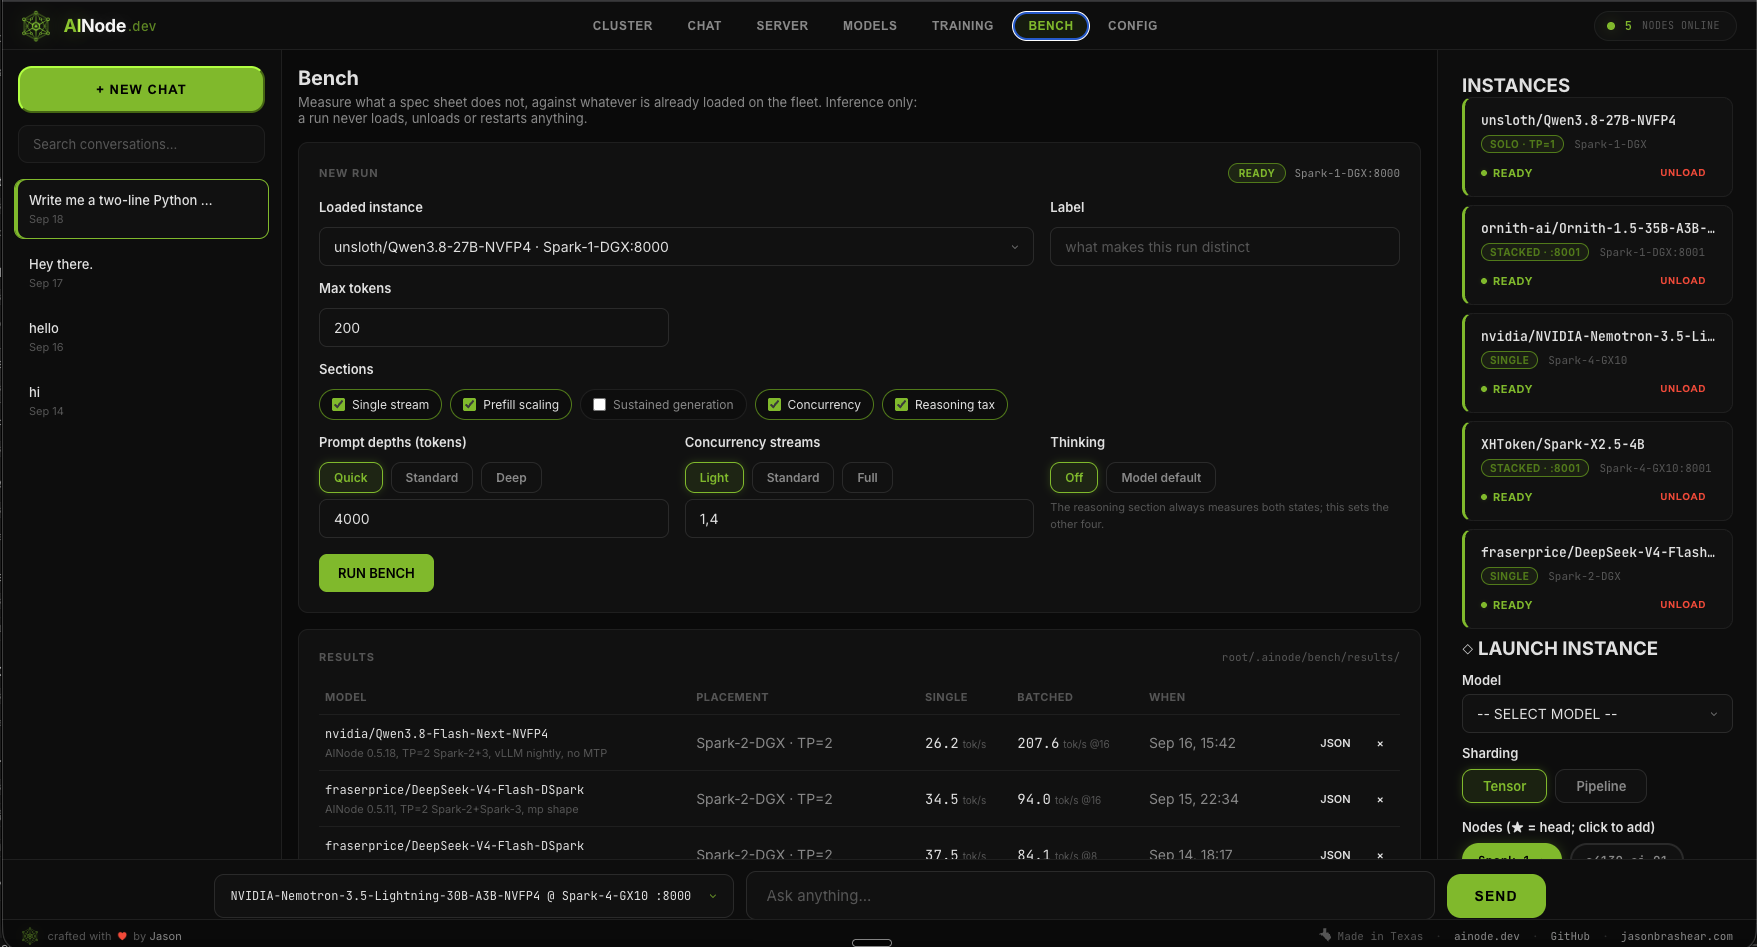
Measure what a spec sheet won't: single-stream speed, concurrency, prefill scaling, and reasoning tax, against whatever is already loaded on the fleet, without disturbing it. Inference only; a run never loads, unloads, or restarts anything.
Every result is saved with full JSON detail. When we publish a throughput number, this is where it came from.
Your Apps Already Speak It
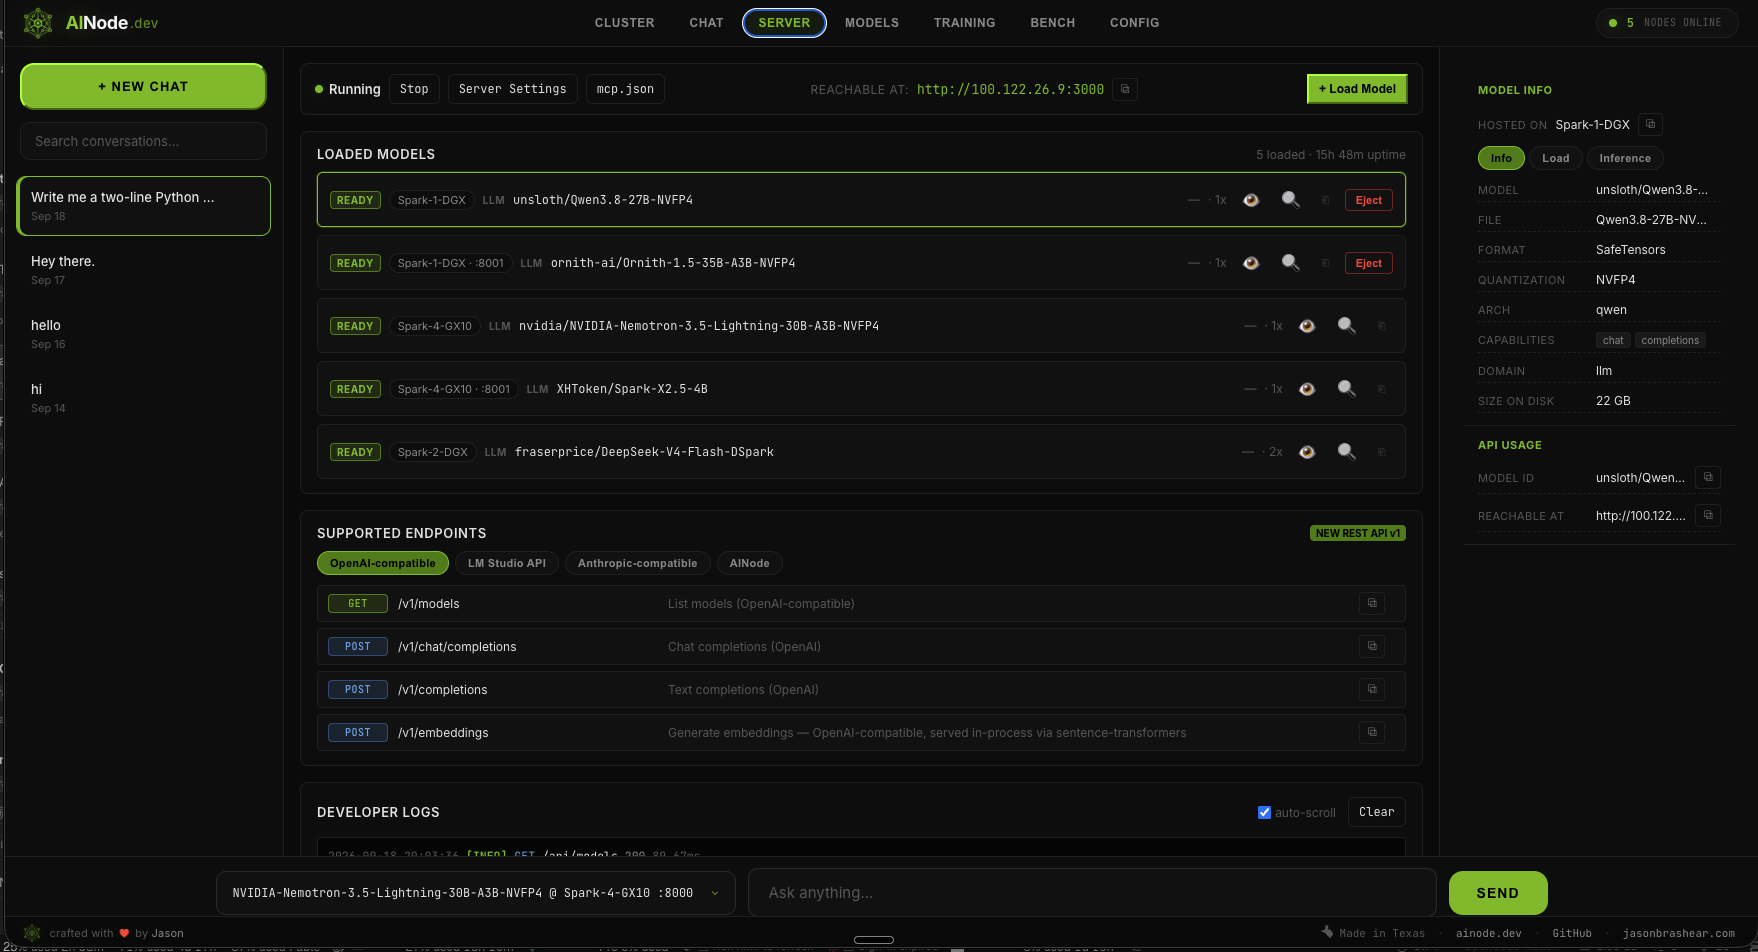
Anything built for the OpenAI API, and most things built for Anthropic or LM Studio, points at your appliance with a one-line change. That's the whole migration.
Why We Built It Ourselves
Off-the-shelf AI servers assume a data scientist is driving. AINode assumes an MSP is accountable: it exposes health, logs, and benchmarks first, and it runs the internal cluster that powers Titanium's own AI operations, so every release is tested on our production workload before it reaches yours.
See AINode Driving Real Hardware
Book a live demo and watch your questions answered by models running on the appliance we'd install in your rack.